Skip to content

A practical perspective for individuals

Less monitoring. More value.

We turn new tools and features into one question: what can you do with them today, without unnecessary hype?

  • AvailabilityIs it actually out?
  • BenefitWhat work could this improve?
  • First stepWhat is worth verifying?
939 practical events in the selection 72 active sources Updated

Practical radar

What deserves your attention

Browse the archive →
Amazon context Productivity

Amazon Bedrock Managed Knowledge Base can search CSV and Excel tables

AWS has added a tabular search feature to Amazon Bedrock Managed Knowledge Base that searches CSV, XLSX, and XLS tables and combines the results with facts from documents using agentic retrieval.

What you get out of it

For developers and analysts working with Amazon Bedrock Managed Knowledge Base, there is now an option to query CSV/Excel files via AgenticRetrieveStream and get an answer backed by calculations over the entire table as well as citations from documents, without having to build their own integration with a BI tool.

✓ official
Details and sources →
GitHub context Coding

Microsoft C++ Language Server in GitHub Copilot CLI now automatically configures MSBuild

The Microsoft C++ Language Server for GitHub Copilot CLI now generates the configuration for MSBuild projects in C++ itself. Manual preparation of compile_commands.json and running a separate configuration skill are no longer needed.

What you get out of it

A C++ developer using GitHub Copilot CLI with an MSBuild project no longer has to manually prepare compile_commands.json or search for and run a configuration skill – according to GitHub, the server now handles this automatically.

✓ official
Details and sources →
xAI context New models

The company xAI has released Grok 4.7 with a lower price but weaker benchmark results than Claude and GPT-6

The company xAI has released Grok 4.7 at $2/million input tokens and $6/million output tokens. On the Artificial Analysis index (v4.3.2), it achieves a score of 46, while Claude Fable 5.1 and GPT-6 lead with a score of 53 each. In the agentic coding test Terminal-Bench 4.0, it scores only 26 %.

What you get out of it

A developer considering a model for agentic coding tasks should take into account that the lower price of Grok 4.7 goes hand in hand with a significantly lower score in Terminal-Bench 4.0 compared with Claude and GPT-6.

1 source
Details and sources →
context Tools and apps

Amazon Bedrock launches a tool for automatic prompt optimization and migration between models

Amazon Bedrock introduced Advanced Prompt Optimization – a tool that automatically optimizes prompts for up to 5 models at once and compares quality, latency (TTFT) and price to simplify migration to new models.

What you get out of it

A developer tuning prompts for applications built on Amazon Bedrock can now have optimization and model comparison performed automatically instead of going through a manual cycle of rewriting and testing, saving time with every prompt adjustment or model change under consideration.

1 source
Details and sources →
Amazon context Tools and apps

Amazon launches a leaderboard for comparing LLM models in SageMaker JumpStart

Amazon has launched the Model Leaderboard tool in SageMaker Studio, which compares over 70 LLM models according to the BIG-Bench Hard, GPQA Diamond, and MMLU-Pro benchmarks and displays the estimated deployment speed and price alongside them.

What you get out of it

A developer working with SageMaker JumpStart no longer has to manually search for and compare benchmarks from various sources — selecting a model for a specific task (chatbot, batch processing) can be done directly in the interface using ready-made profiles.

✓ official
Details and sources →
context Video generation

The company Fountain 0 has released the AI-generated film Odysseus: The Fall; a review criticizes technical errors

The company Fountain 0 has released the 2.5-hour AI-generated film Odysseus: The Fall, which it describes as the first “Hollywood" AI blockbuster. The review by The Verge describes frequent errors: changing character dimensions, mouths out of sync, bending oars, and incorrect pronunciation of names. Rental costs 9.99 USD.

What you get out of it

For those interested in the state of AI-generated video, the film serves as a concrete example of what a fully AI-generated feature-length production looks like in practice and what errors (inconsistencies, poor synchronization, incorrect pronunciation) appear in it according to the review.

1 source
Details and sources →
GitHub context Tools and apps

GitHub Copilot: general availability of Lite and Balanced levels of detail for code review

GitHub has made the Lite and Balanced levels of detail for GitHub Copilot code review generally available (GA) – they allow the depth of pull request reviews to be chosen based on complexity. Available in the Pro, Pro+, Max, Business and Enterprise plans; admins can set a default level for the entire organization.

What you get out of it

Each time developers request a code review from GitHub Copilot, they can choose the depth of analysis based on the nature of the change, allowing them to get faster feedback on minor edits and a more thorough examination of complex or risky code.

✓ official
Details and sources →
context Tools and apps

Grokipedia v0.3 update changes the look and overview of articles and edits

Grokipedia version v0.3 has received a new logo and a homepage with a selection of articles, most-read articles, and recent edits. The live edits page shows multiple changes at once; article pages have updated tables and smaller line spacing.

What you get out of it

When using Grokipedia, you can select articles from the new overviews on the homepage and view multiple recent edits at the same time.

1 source
Details and sources →
context Open-source

LLM 0.37: new models, a cheaper default model, and better multimodal embeddings

Version 0.37 of the LLM CLI tool by Simon Willison adds the models gpt-6.1-sol and gpt-6.1-terra, a cheaper default model gpt-6-luna, and better support for multimodal embeddings (text, audio, image, video).

What you get out of it

After updating, users of the LLM CLI tool can use the new models gpt-6.1-sol and gpt-6.1-terra, more easily add OpenAI-compatible endpoints with the command llm openai endpoint add, and pay less for the default model if they have not set their own default.

1 source
Details and sources →
context Tools and apps

Bolt introduces ride booking through a plugin in ChatGPT

Bolt has launched ride booking through a plugin in ChatGPT, available in Czechia too. It displays the price, route and driver arrival, and the booking is completed in the Bolt app; according to the company, payment through ChatGPT is expected to be added later this year.

What you get out of it

ChatGPT users in Czechia and other countries can now book a Bolt ride directly in the conversation after installing the plugin, but completing the booking and paying still take place in the Bolt app.

1 source
Details and sources →
Google context Tools and apps

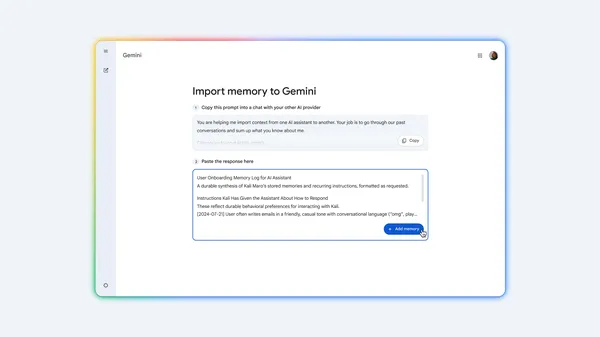
Google has launched a feature for importing chat history from other AI assistants into the Gemini product

Google has launched a feature in the Gemini product for importing chat history and preferences from other AI assistants using a ZIP file export and a special prompt, intended to make switching easier without losing previous conversations.

What you get out of it

A user switching to the Gemini product from another AI assistant doesn't have to start from scratch and can carry over their existing preferences as well as chat history.

1 source
Details and sources →
major update Regulation and law

AI Act: shortly after mandatory labeling of AI content is introduced, tools emerge to circumvent it

Shortly after mandatory labeling of AI content under Article 50 AI Act was introduced, tools emerged to remove it. According to the source, Grok from Elon Musk ignores labeling, which may paradoxically favor models beyond the reach of EU regulation, such as Chinese models.

New: Tools exist that can remove or cover up mandatory AI labels; Labeling of AI content works through invisible characters and non-random word selection; AI Act regulation may become ineffective because of circumvention techniques; Grok from Elon Musk ignores mandatory labeling; The regulation may paradoxically favor Chinese models outside the scope of EU rules

What you get out of it

The presence or absence of mandatory labeling of AI content is no longer a reliable guide, because according to sources, tools exist that can remove such markers, and some models (Grok) ignore them according to information from the source.

✓ 3
Details and sources →

When personal experience proves useful

Does it make sense for a team too?

Look at the same topics through the lens of processes, risks, and implementation within a company.

Go to the company radar →