

Liquid AI releases two text understanding models with a context length of 8 192 tokens
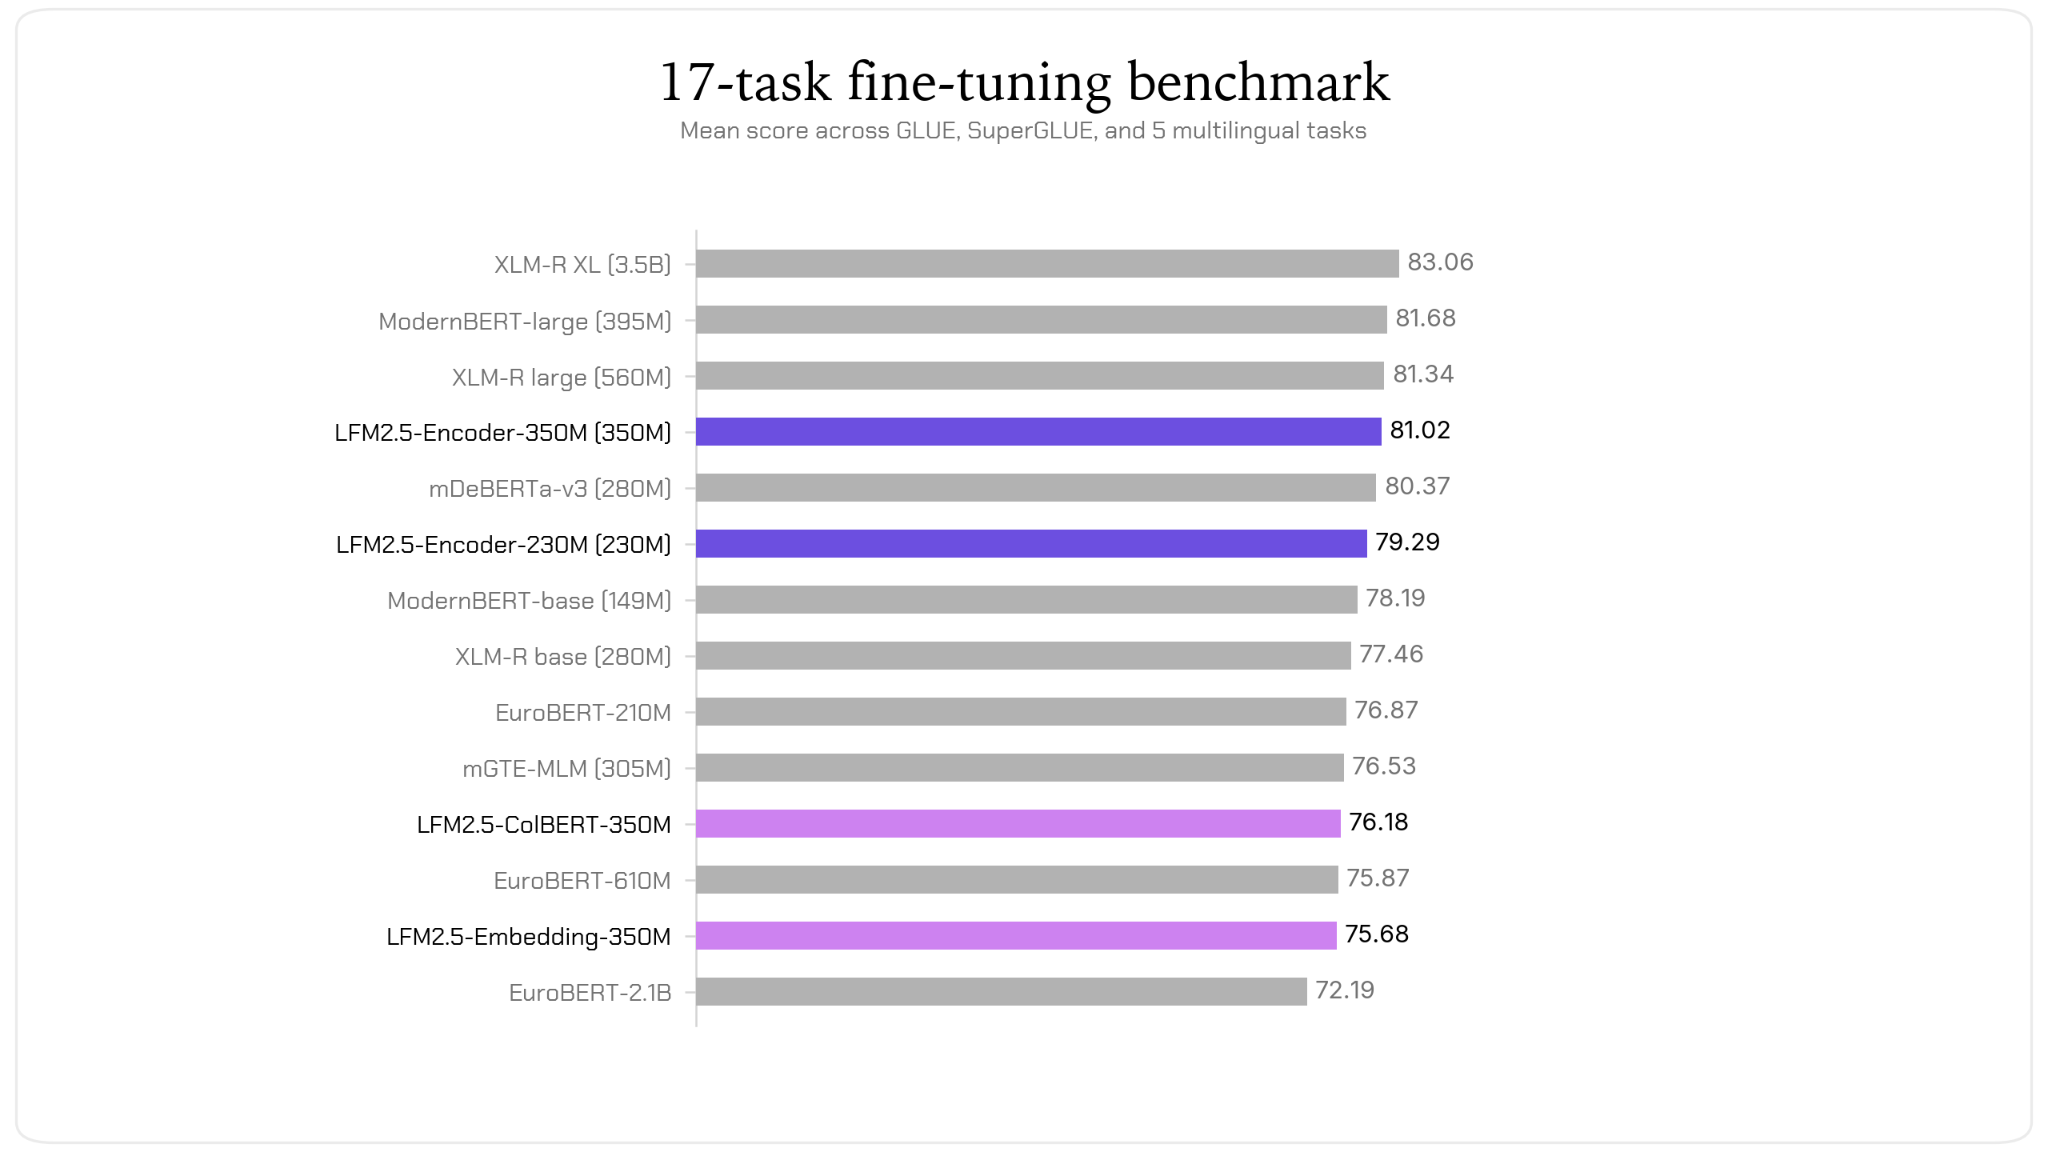
Liquid AI has released LFM2.5-Encoder-230M and LFM2.5-Encoder-350M, designed to be fine-tuned for classification and other text understanding tasks. They support 8 192 tokens and, according to the company, process long inputs faster than the models used for comparison, even on a CPU.
Liquid AI has released LFM2.5-Encoder-230M and LFM2.5-Encoder-350M for classification, text understanding and token-level tasks. These are bidirectional models designed to be fine-tuned for a specific task, with support for a context length of 8 192 tokens.
Both models are based on the hybrid LFM2 architecture. During processing, they use context both before and after a token. Training included predicting masked tokens, which made up 30 % of the input, followed by extending the context from 1 024 to 8 192 tokens.
According to measurements by Liquid AI, LFM2.5-Encoder-350M ranked fourth among 14 models compared in an evaluation covering 17 tasks; each model was fine-tuned separately for each task. The company also reports that, for an input of 8 192 tokens, computation with LFM2.5-Encoder-230M on a CPU took approximately 28 seconds, compared with over a minute and a half for ModernBERT-base. These are results from the developer, not independent verification. Details are available in the source article.
Why it matters
According to the source, document classification, intent recognition and content filtering are among the tasks that often run on CPUs. If the reported performance is confirmed in a specific deployment, the new models could make it easier to process longer inputs on existing hardware, including in environments where sensitive documents must remain within the organization.
Two audiences, two different impacts
What this means
For individuals
Developers gain two new starting points for building a custom classifier or processing individual tokens. When choosing a model, its quality after fine-tuning for the specific task is important, because that is how the company evaluated the models.
For a business
For companies processing long internal documents, this offers another option for CPU deployment on their own infrastructure. Any potential benefits for hardware costs and processing capacity depend on performance in their operating environment.
ProcessesCheck the original
Event sources
clearly official source · 1 publisher, 0 independent. We count feeds from the same owner only once.