

Liquid AI has made Liquid RIPL available for running LFM models on NVIDIA GPUs
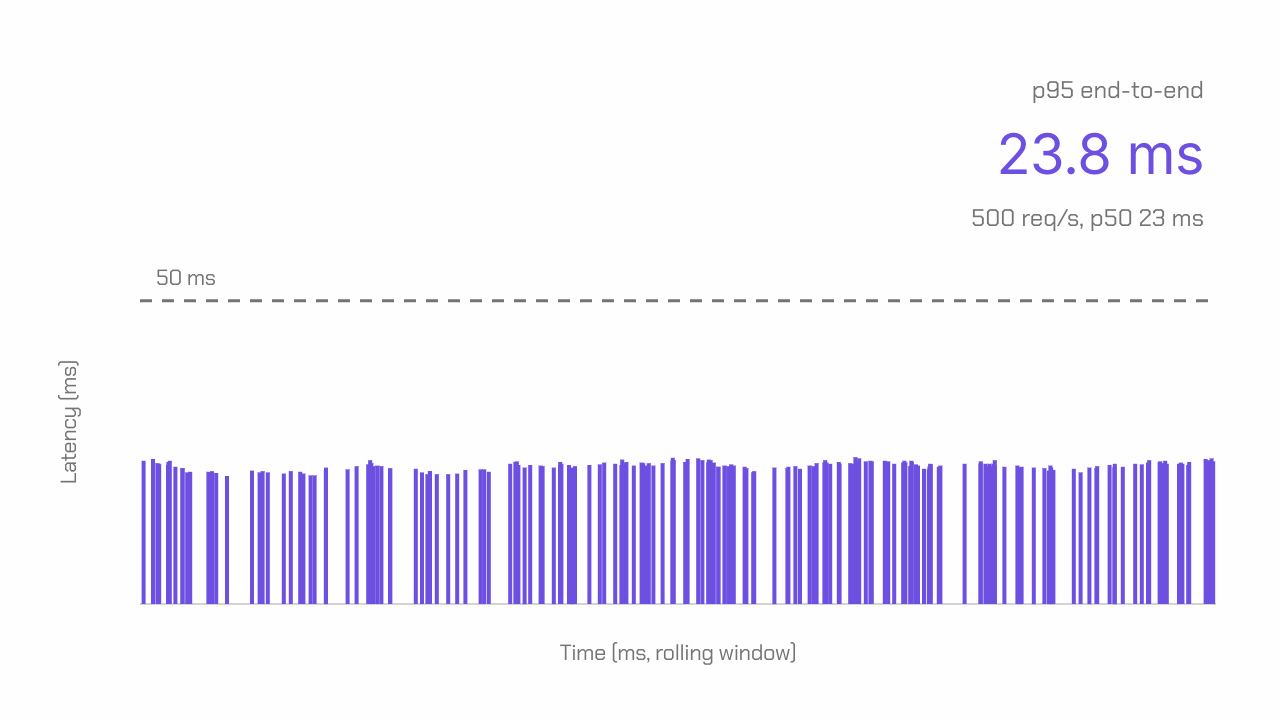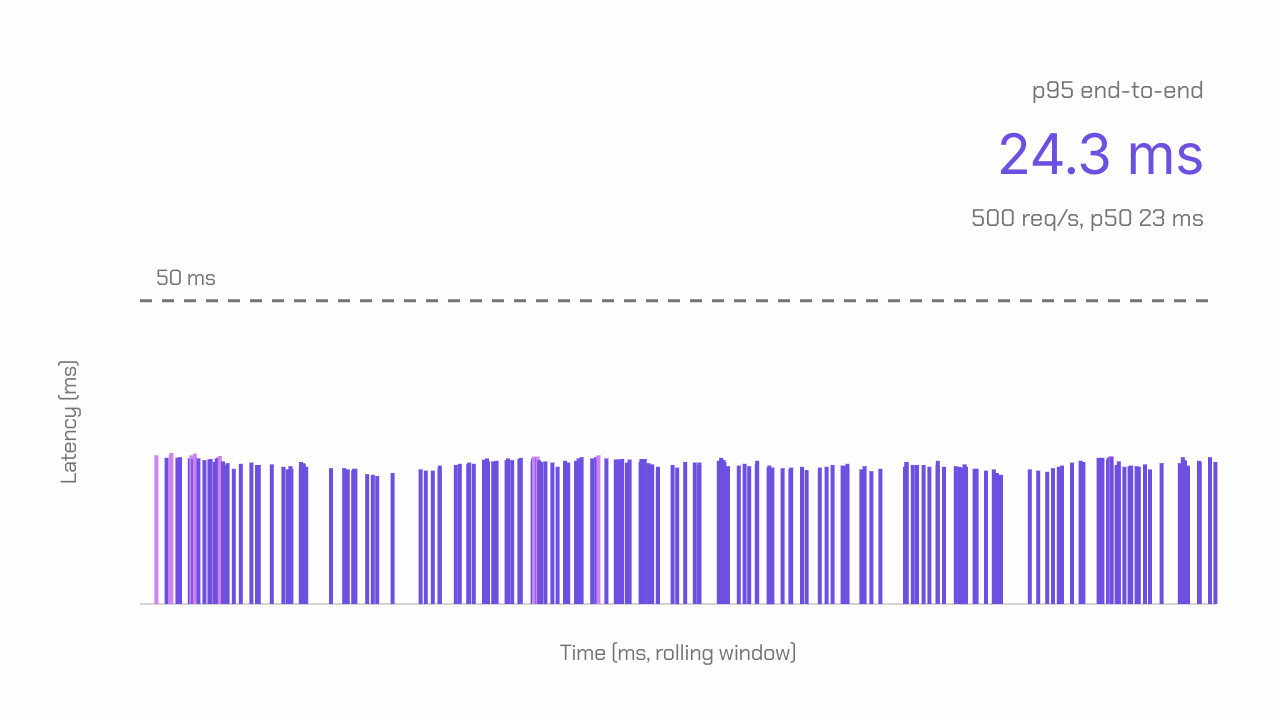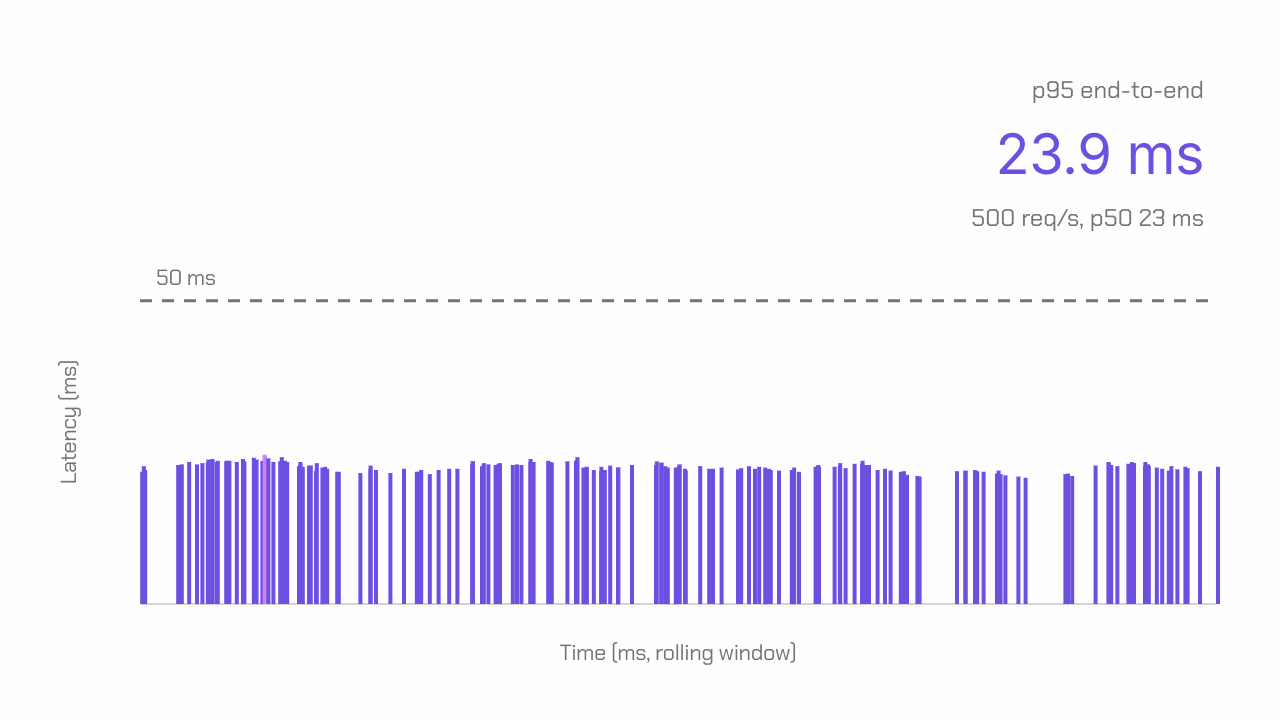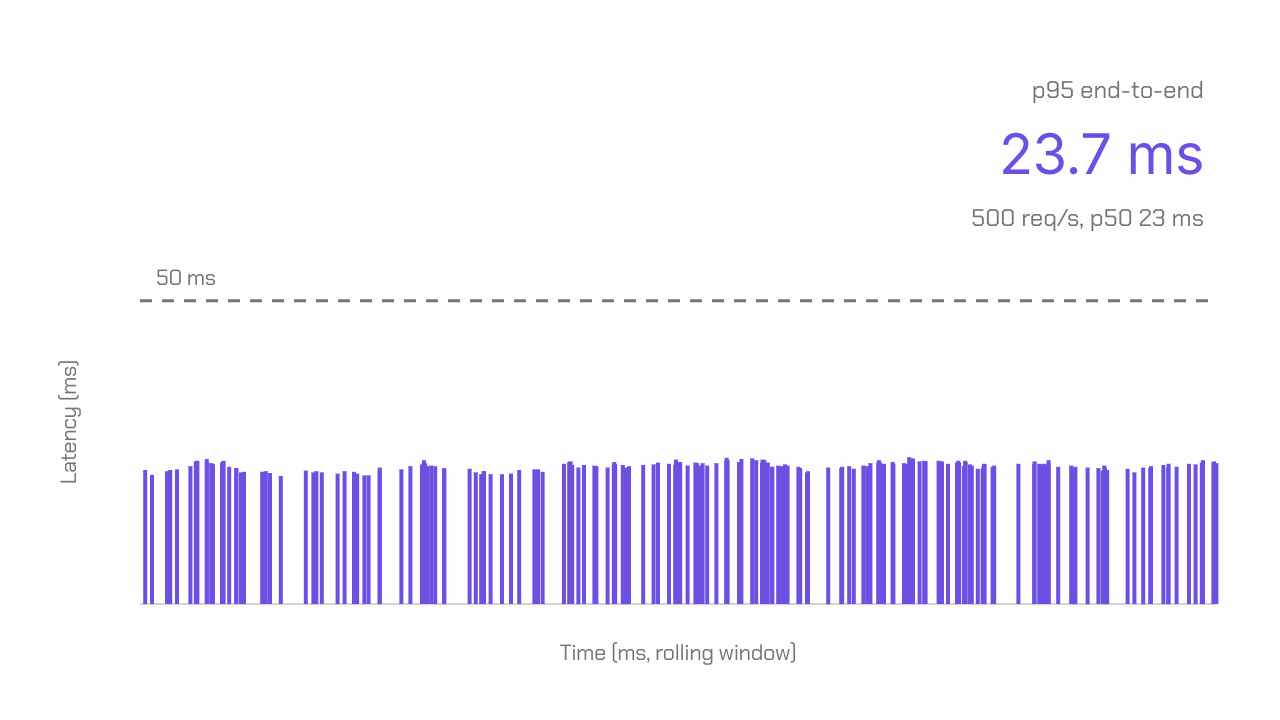
Liquid AI has made Liquid RIPL available for enterprise deployment of LFM models on NVIDIA GPUs. According to the company, the tool returns complete responses in less than 50 ms even at peak load. Supported GPUs include H100, H200, B200 and RTX PRO 6000.
Liquid AI has made Liquid RIPL available, a tool for fast request processing using LFM models in enterprise environments. It is available for NVIDIA GPUs, including H100, H200, B200 and RTX PRO 6000. According to the company, it can return complete generated responses in less than 50 ms even with a continuous stream of requests at peak load.
In two published test workloads, the company reported that LFM2.5-1.2B running with Liquid RIPL had 14.4–28.4 times lower p95 latency than Qwen3.5-0.8B running with vLLM. For LFM2.5-2.6B, the company reports 5.6–7.7 times lower p95 latency compared with Qwen3.5-2B running with vLLM. The p95 metric indicates the time within which 95 % of responses are returned. The comparison therefore includes different models as well as different tools for running them; it is not an isolated measurement of the benefit of Liquid RIPL.
Why it matters
The tool targets search, product recommendations, fraud detection and payment authorization, where model responses must fit within a strict time budget. Enterprise teams can test the use of LFM models directly during request handling; however, the published results are vendor measurements for specific workloads.
Relevant practical impact
What this means
For a business
Companies with supported GPUs now have another option for testing generative models in latency-sensitive processes. Deployment decisions must be based on latency and quality under their own operational load.
ProcessesCheck the original
Event sources
only one source so far · 1 publisher, 0 independent. We count feeds from the same owner only once.