

OpenAI makes the GPT-6 Astra Ultrafast model available via API and to selected users
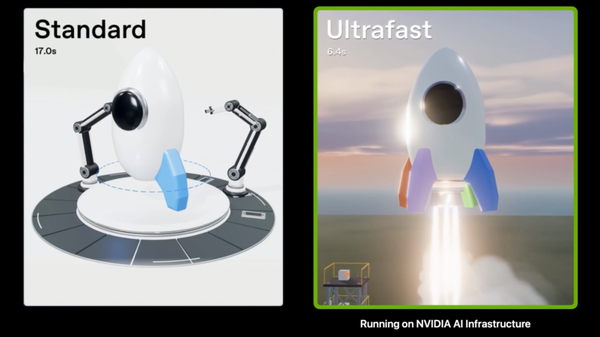
The GPT-6 Astra Ultrafast model is available in OpenAI API and to eligible users of ChatGPT Work and Codex. It runs on NVIDIA Blackwell GPU and, according to NVIDIA, offers up to 8× faster token generation than Astra Standard mode.
The GPT-6 Astra Ultrafast model is now available in OpenAI API and to eligible users of ChatGPT Work and Codex. Access in these services has therefore not been announced for all users.
The model runs on NVIDIA Blackwell GPU. According to NVIDIA, it uses inference optimizations and the capabilities of this architecture to generate tokens up to 8× faster than Astra Standard mode. This comparison concerns token generation speed, not the total time to complete a task. You can find details in the source article.
Why it matters
Faster token generation may reduce the wait for responses when working in ChatGPT Work and Codex. Availability through OpenAI API allows companies to test the benefit for the response time of their own applications; the figure of up to 8× is a claim by NVIDIA about token generation.
Release card
GPT-6 Astra Ultrafast
OpenAI
- Availability
- The model is now available in OpenAI API and to eligible users of ChatGPT Work and Codex.
- Rychlost generování tokenů Až 8× rychlejší než režim Astra Standard According to NVIDIA, the model generates tokens up to eight times faster than Astra Standard mode.
The source compares the model with Astra Standard mode in terms of token generation speed.
The card summarizes information from the article and any dated corrections, with a link to the original source. It is not our assessment of the model. It does not yet have a dedicated editorial profile. Model selection and other announcements →
Two audiences, two different impacts
What this means
For individuals
If you have eligible access to ChatGPT Work or Codex, you can use the GPT-6 Astra Ultrafast model and assess whether faster response generation makes your everyday work easier.
For a business
Availability through OpenAI API gives development teams the opportunity to test response generation speed in their own applications. The claimed speedup alone does not demonstrate the same benefit for the entire business process.
DevelopmentCheck the original
Event sources
clearly official source · 1 publisher, 0 independent. We count feeds from the same owner only once.